Bridging Vision‑Language‑ActionModels and Whole-Body Controllervia Structured Action Interfaces
Anonymous authors
Overview
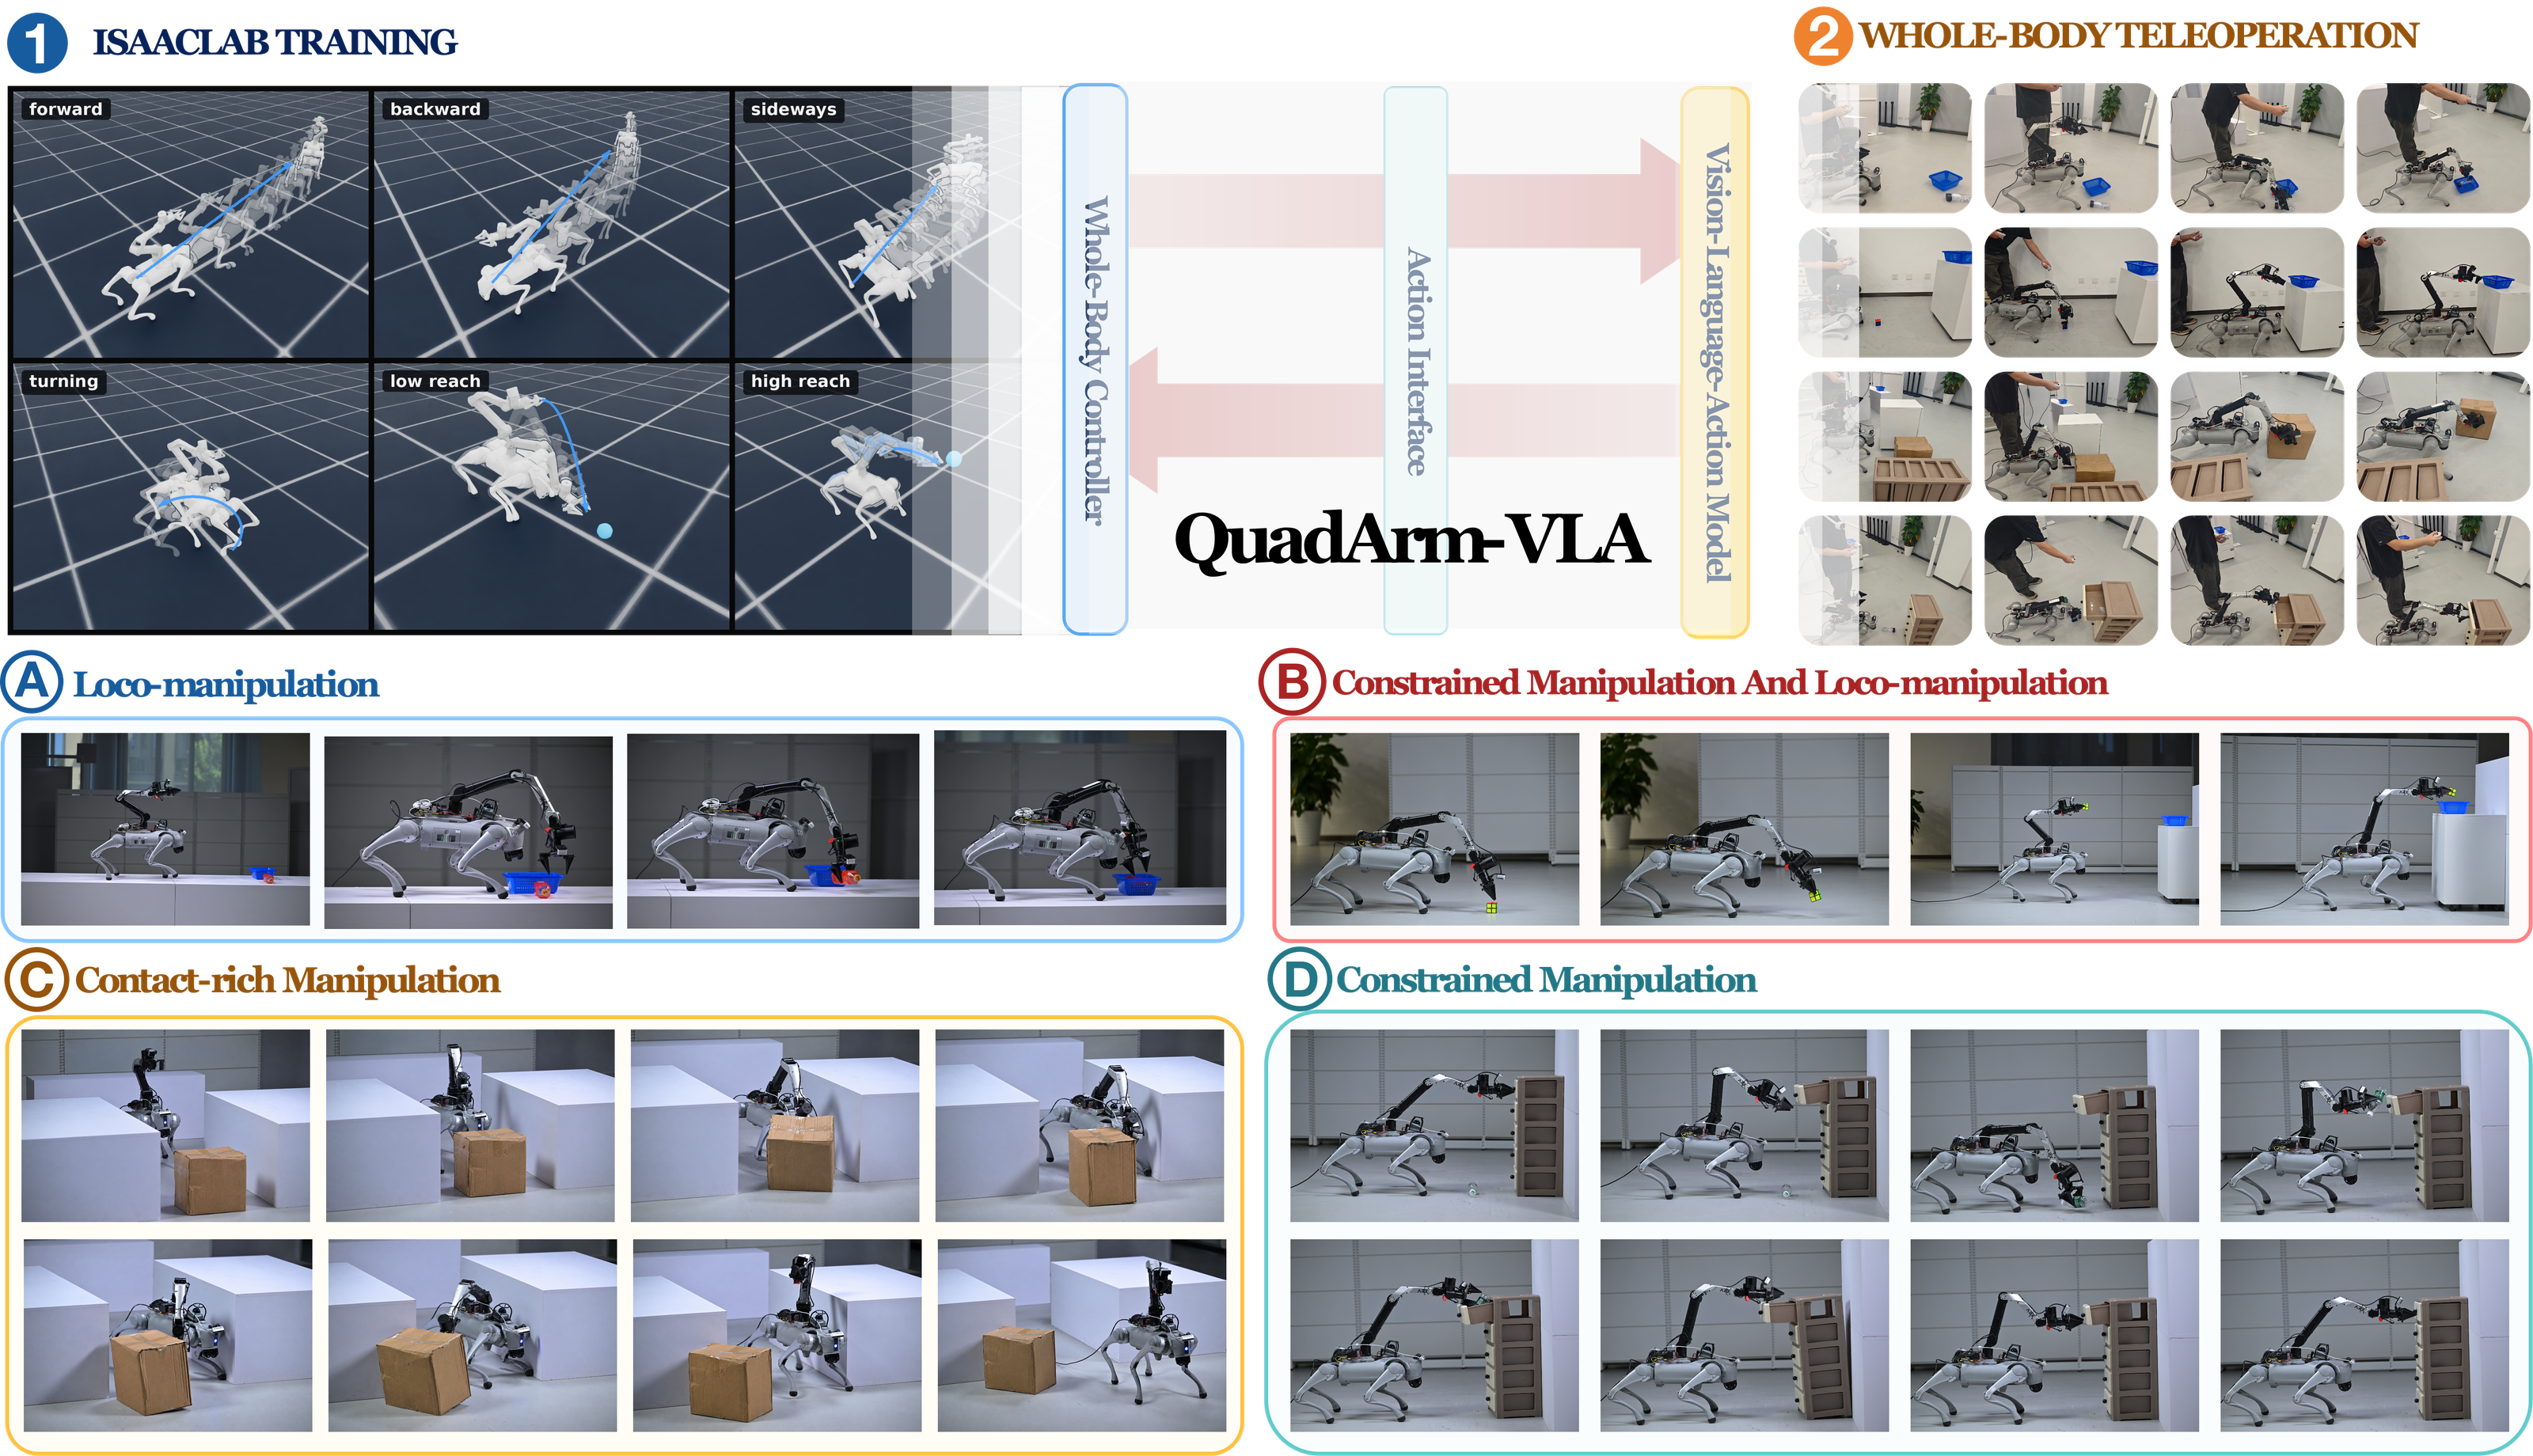
Overview of QuadArm-VLA.
We acquire embodiment-specific arm-body coordination through large-scale IsaacLab training and collect whole-body demonstrations through teleoperation.
A pretrained vision-language-action model is then adapted to the resulting controller interface.
QuadArm-VLA supports (A) mobile pick-and-place, (B) small-object transport and elevated placement, (C) contact-rich box pushing around an obstacle, and (D) drawer opening, object placement, and drawer closing.